TL;DR
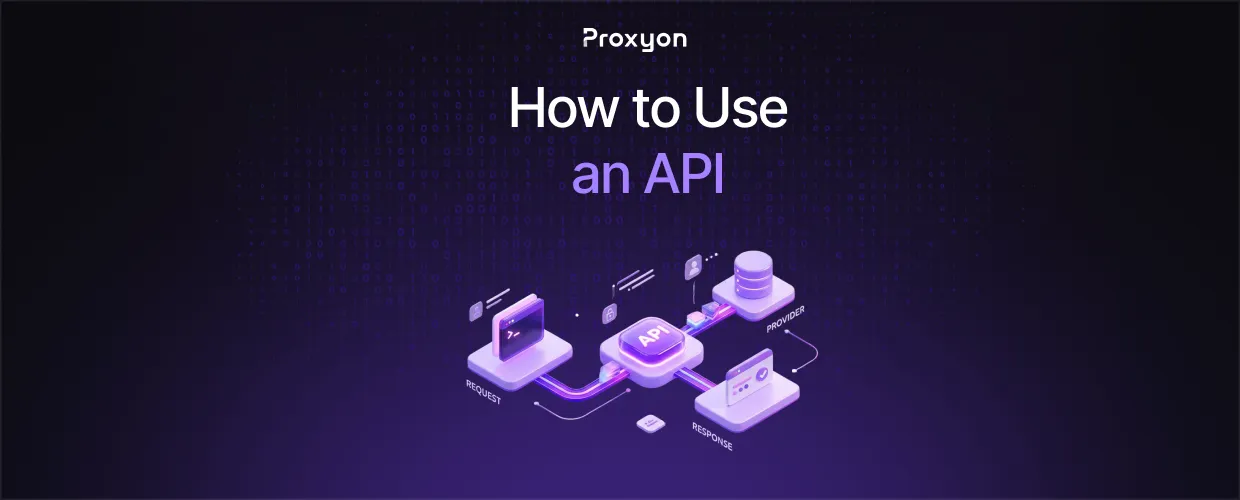
An API is a defined set of rules that lets one piece of software request data or actions from another. You send a request to an endpoint, the server processes it, and you get a response back, usually in JSON.
Understanding the Basics
Most APIs you will work with are REST APIs. They use standard HTTP methods: GET to retrieve data, POST to create something, PUT or PATCH to update it, DELETE to remove it. The endpoint URL tells the server what resource you are asking about.
Every request typically needs a base URL, a method, and often a set of headers. Headers carry metadata like content type and authentication tokens. The response comes back with a status code, and the code tells you what happened before you even look at the body. A 200 means success, a 401 means your credentials failed, a 429 means you are being rate limited.
Also Read: How to Scrape JavaScript-Heavy Sites With Playwright and Proxies (2026)
Authenticating Your Requests
Most APIs require an API key or token. You get this from the provider's dashboard after signing up. The key usually goes in a header, most commonly Authorization: Bearer YOUR_KEY, though some older APIs still accept it as a query parameter.
Never hardcode your key directly into a script you plan to share or commit. Use an environment variable instead and load it at runtime. This is a basic habit worth building early, since leaked keys are one of the most common ways developers rack up unexpected charges.
Making Your First Request
Here is a minimal example using Python's requests library:
import requests

headers = {"Authorization": "Bearer YOUR_KEY"}
response = requests.get("https://api.example.com/v1/data", headers=headers)

print(response.status_code)
print(response.json())
Check the requests documentation for how to handle query parameters, timeouts, and sessions. Most production code wraps this in a retry loop, since networks fail and rate limits happen.
Handling Errors and Rate Limits
The downside of calling any API at volume is that you will eventually hit a wall: timeouts, rate limits, or temporary server errors. Read the response headers before retrying blindly. Many APIs return a Retry-After header telling you exactly how long to wait, which is part of the standard HTTP status code spec.
If you are calling an API repeatedly from the same IP for large-scale data collection, some providers will throttle or block you regardless of your rate limit compliance. This is where residential proxies come in, since they let you spread requests across different IPs instead of hammering one address. It matters more for scraping-style workloads than for typical app-to-app API integration.
For high-volume, cost-sensitive workflows where the target does not run heavy anti-bot checks, datacenter proxies are worth a look too. Plans start from $0.30 per IP for 3 days with unmetered bandwidth, so they cost less per thread than residential IPs, which adds up fast if you are pulling data at scale.
Also Read: Mobile Proxies Explained: How They Work & How to Use Them
FAQ Section
What is the difference between an API key and OAuth?
An API key is a static credential tied to your account. OAuth is a token-based flow that can expire and be scoped to specific permissions. Keys are simpler; OAuth is more secure for user-facing apps.
Why am I getting a 429 error?
You have hit the provider's rate limit. Slow down your request rate, check for a Retry-After header, and add backoff logic to your retries.
Do I need a proxy to use an API?
Not for normal usage. Proxies become relevant when you are making a high volume of requests and need to avoid IP-based blocking or rate limiting, which is common in scraping but not in standard app integrations.
Final Thoughts
Using an API comes down to three things: authenticate correctly, respect the rate limits, and handle errors instead of assuming every request succeeds. Get those right and the rest is just reading the specific provider's documentation for their endpoints and data format.