TL;DR
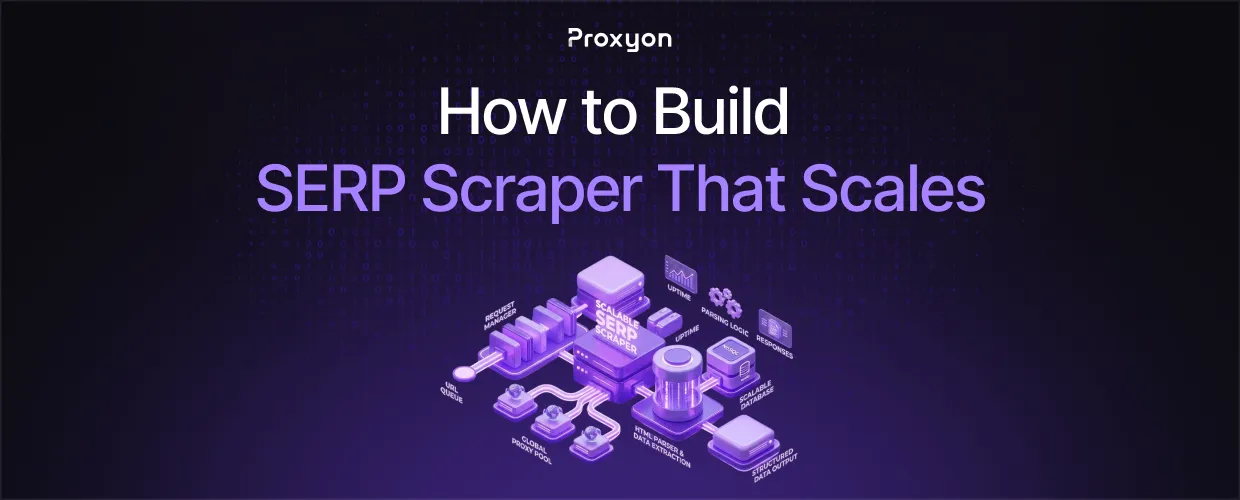
SERP scraping is the process of pulling structured data out of search engine results pages, rankings, snippets, ads, and related searches, at volume and on a schedule.
Most teams start by hitting Google directly with a script and a requests.get() call. That works for a handful of queries. It breaks the moment you need thousands of keywords tracked daily, because Google fingerprints and blocks scraped traffic fast. Building something that actually scales comes down to three things: how you route your requests, how you manage concurrency, and how you handle failure.
Also Read: How to Do Web Scraping Without Getting Blocked
Why Google Blocks SERP Requests
Google doesn't need much to flag a scraper. A handful of requests from the same IP in a short window, a missing or generic user agent, or a request pattern that doesn't look like a real browsing session are all enough. Google's own Search Central guidelines state plainly that automated queries aren't permitted without prior authorization, which is the policy basis behind the blocking behavior.
The response is usually a CAPTCHA page instead of real results, or a hard block on that IP. Once an IP is flagged, every request from it fails the same way, which is why single-IP setups collapse under any real workload.
This is a routing problem before it's a parsing problem. Fix the IP layer first, and the rest of the pipeline gets a lot simpler.
Rotating Proxies for Scraping
A scalable SERP setup needs a new IP for close to every request, not just when one gets blocked. Residential proxies work best here because the request comes from a real ISP-assigned IP, which looks like normal user traffic to Google instead of server traffic.
Datacenter IPs are cheaper per unit, but Google's detection systems flag datacenter ranges more aggressively on search results specifically. That trade-off matters more for SERP work than for scraping less defended targets. If your volume is high enough that residential bandwidth costs add up, IPv6 rotating proxies are worth testing on a subset of your traffic, since they're priced per thread rather than per GB.
Structuring Requests for Concurrency
Once IP rotation is handled, the next bottleneck is how you send requests. A sequential loop querying one keyword at a time will never scale past a few hundred keywords a day. You need concurrent requests, each carrying its own IP from the pool, with rate limits per proxy rather than a global limit. Python's ThreadPoolExecutor is a solid default for this since SERP requests are I/O-bound, not CPU-bound.
import requests
from concurrent.futures import ThreadPoolExecutor

PROXY = "http://user:pass@proxy.proxyon.io:8080"

def fetch_serp(keyword):
    params = {"q": keyword, "hl": "en", "gl": "us"}
    headers = {"User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64)"}
    response = requests.get(
        "https://www.google.com/search",
        params=params,
        headers=headers,
        proxies={"http": PROXY, "https": PROXY},
        timeout=15,
    )
    return response.text

keywords = ["serp scraping", "residential proxy api", "web scraping tools"]

with ThreadPoolExecutor(max_workers=10) as pool:
    results = list(pool.map(fetch_serp, keywords))
Each thread pulls a session through Proxyon's rotating endpoint, so every request in the pool gets a different IP automatically. You don't manage a proxy list manually. The endpoint handles rotation on its end.
Set max_workers based on your proxy plan and target response times, not arbitrarily high. Too many concurrent threads against the same target window increases block rates even with rotation, since Google also rate-limits by broader traffic patterns, not just single IPs.
Buy an API or Build Your Own
Managed SERP APIs handle rotation, parsing, and retries for you, and they're a reasonable option if you need results now and don't want to maintain infrastructure. The trade-off is cost per query and less control over request patterns, which matters if you're tracking tens of thousands of keywords.
Building your own SERP scraper on top of a proxy provider costs more engineering time upfront but scales at a lower marginal cost, since you're paying for bandwidth or IPs, not a per-query markup. For teams already comfortable with scraping infrastructure, this is usually the cheaper path past a certain volume.
FAQ Section
Is SERP scraping legal?
Google's terms of service prohibit automated queries without permission, so scraping violates their terms even though it's not illegal in most jurisdictions. Most SERP scraping operates in that gray area. Rate limit reasonably and expect Google to block or flag traffic that looks automated.
How many proxies do I need for SERP scraping at scale
It depends on volume and concurrency, not a fixed number. A rough starting point is one active IP per 5-10 concurrent requests, scaled up as your keyword count grows. Rotating residential endpoints handle this automatically, so you're sizing bandwidth, not managing a proxy list.
Residential or datacenter proxies for SERP scraping?
Residential, in almost every case. Google flags datacenter IP ranges more aggressively on search results specifically, which makes datacenter proxies a poor fit even though they're cheaper per unit.
What causes the highest block rates in SERP scraping?
Too many requests from one IP in a short window, generic or missing user agents, and request timing that's too consistent to look human. Fix rotation and concurrency first before touching anything else in the pipeline.
Should I build my own SERP scraper or use a managed API?
Build your own once your keyword volume is high enough that per-query API costs outweigh the engineering time. Below that threshold, a managed API is usually cheaper and faster to ship.
Final Thoughts
Scalable SERP scraping comes down to IP rotation, controlled concurrency, and a retry system that doesn't lose data. Build it in-house once your keyword volume justifies the engineering time, and lean on a managed API before that. Either way, the proxy layer is what makes or breaks it. Proxyon runs pay-as-you-go with no subscriptions and no KYC, so you can deposit $5 and test your setup against real traffic before committing to a plan.